Core Reliability Metrics.
Articles in this part of the Intelligence Hub.
Showing 2 of 2 articles.
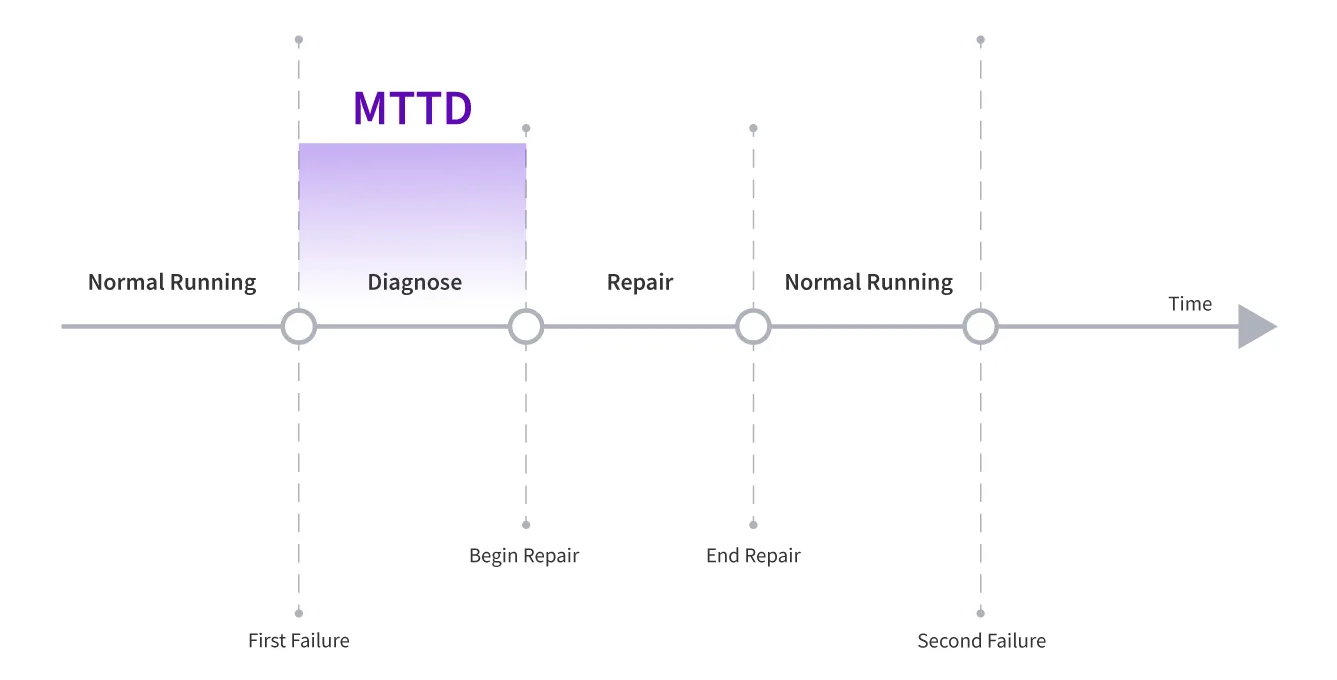
Mean Time to Detect (MTTD): What It Is, Why It Matters, and How Teams Use It
Most incidents don’t start with a loud failure. They begin quietly: an error rate creeping up, a service slowing down, a subtle signal that’s easy to miss. By the time the problem is obvious, the impact is already underway.
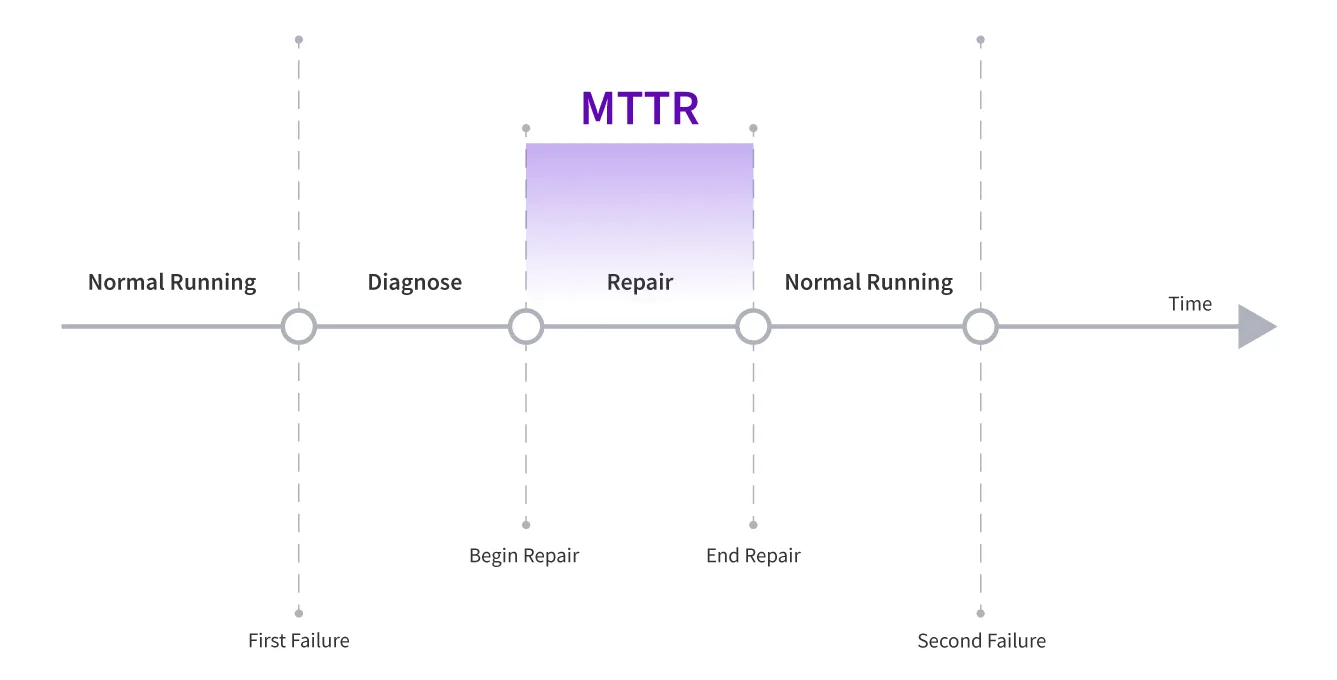
Mean Time to Restore (MTTR): A Practical Guide for Engineering and Technology Leaders
Mean Time to Restore (MTTR) measures the average amount of time it takes for a system or service to recover after a production incident or outage. In simple terms, it reflects how quickly an organization can return to normal operations once something goes wrong.
See it running on your own pipelines.
Forty-five minutes with our engineers. Bring a pipeline you are unhappy with.
Book a demoNo install required