Reliability & Incidents.
Understand how well systems maintain availability and recover from disruption. This category focuses on detection, response, restoration, and incident trends that shape operational resilience.
Every article.
Showing 4 of 4 articles.
Incident Frequency
How often your systems break, why that number lies to you, and what to do about it.
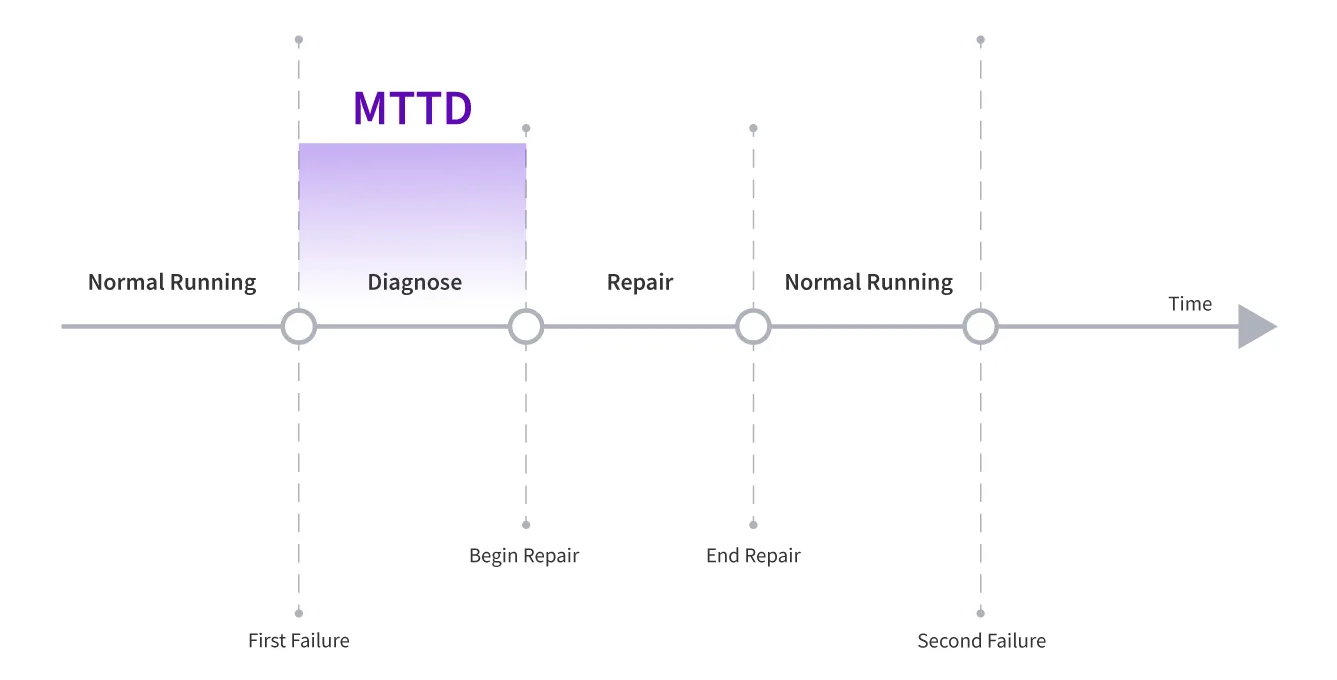
Mean Time to Detect (MTTD): What It Is, Why It Matters, and How Teams Use It
Most incidents don’t start with a loud failure. They begin quietly: an error rate creeping up, a service slowing down, a subtle signal that’s easy to miss. By the time the problem is obvious, the impact is already underway.
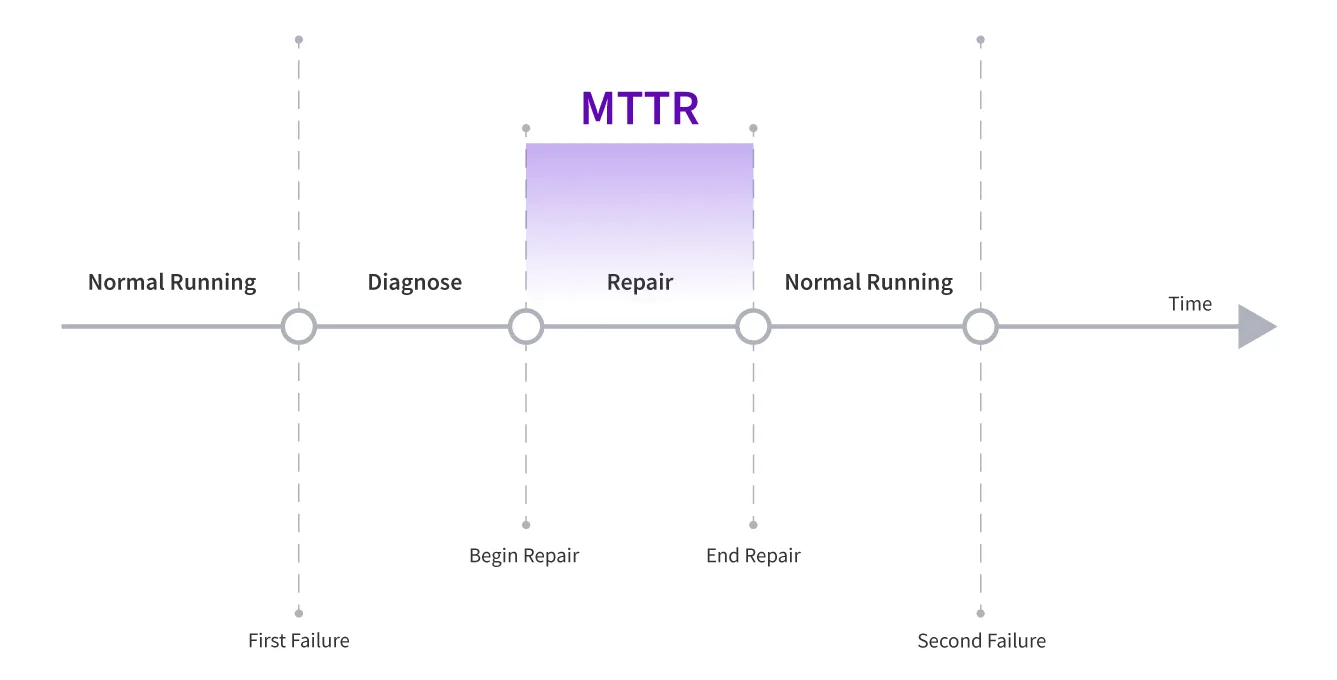
Mean Time to Restore (MTTR): A Practical Guide for Engineering and Technology Leaders
Mean Time to Restore (MTTR) measures the average amount of time it takes for a system or service to recover after a production incident or outage. In simple terms, it reflects how quickly an organization can return to normal operations once something goes wrong.
Repeat Incident Rate
The metric that tells you whether your incident process is actually working or just generating documentation.
Get started.
When something goes wrong in production, two questions immediately matter: how long did it take to find out, and how long did it take to fix it? This section covers the core reliability metrics — MTTD, MTTR, and the incident patterns that underlie them—that engineering and operations teams use to understand system resilience and improve their response over time. Whether you're building the case for better observability tooling or trying to reduce the blast radius of incidents when they do occur, these are the numbers that tell you how your systems hold up under pressure.
See it running on your own pipelines.
Forty-five minutes with our engineers. Bring a pipeline you are unhappy with.